token optimization
LLM Guardian
Token-cost guardian for LLM inference. Sits between your app and the provider — compressing prompts, injecting MemOS context packs, and enforcing token budgets, all locally.
Quick start
$ npm install -g llm-guardian
$ guardian start
# OpenAI-compatible proxy on localhost — point your app at it
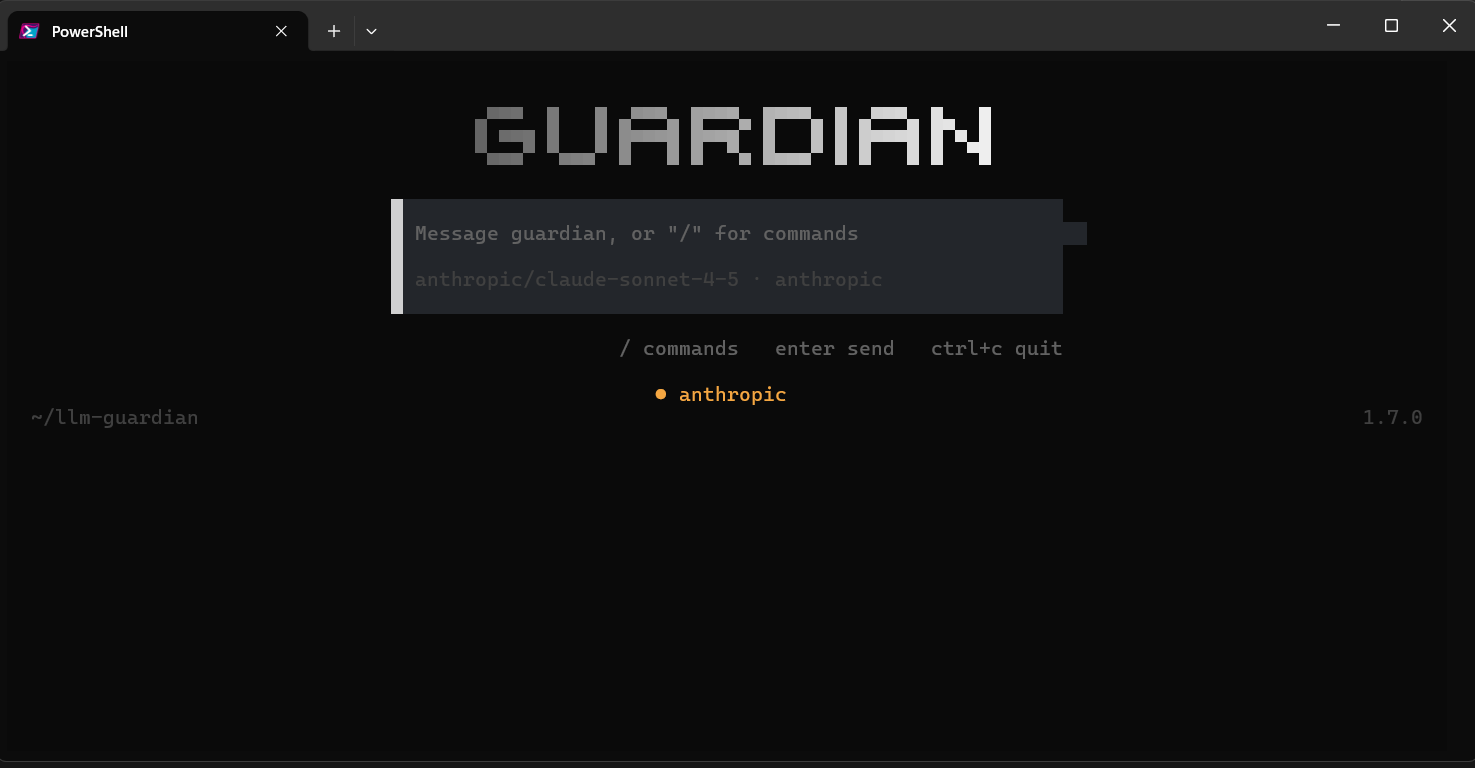
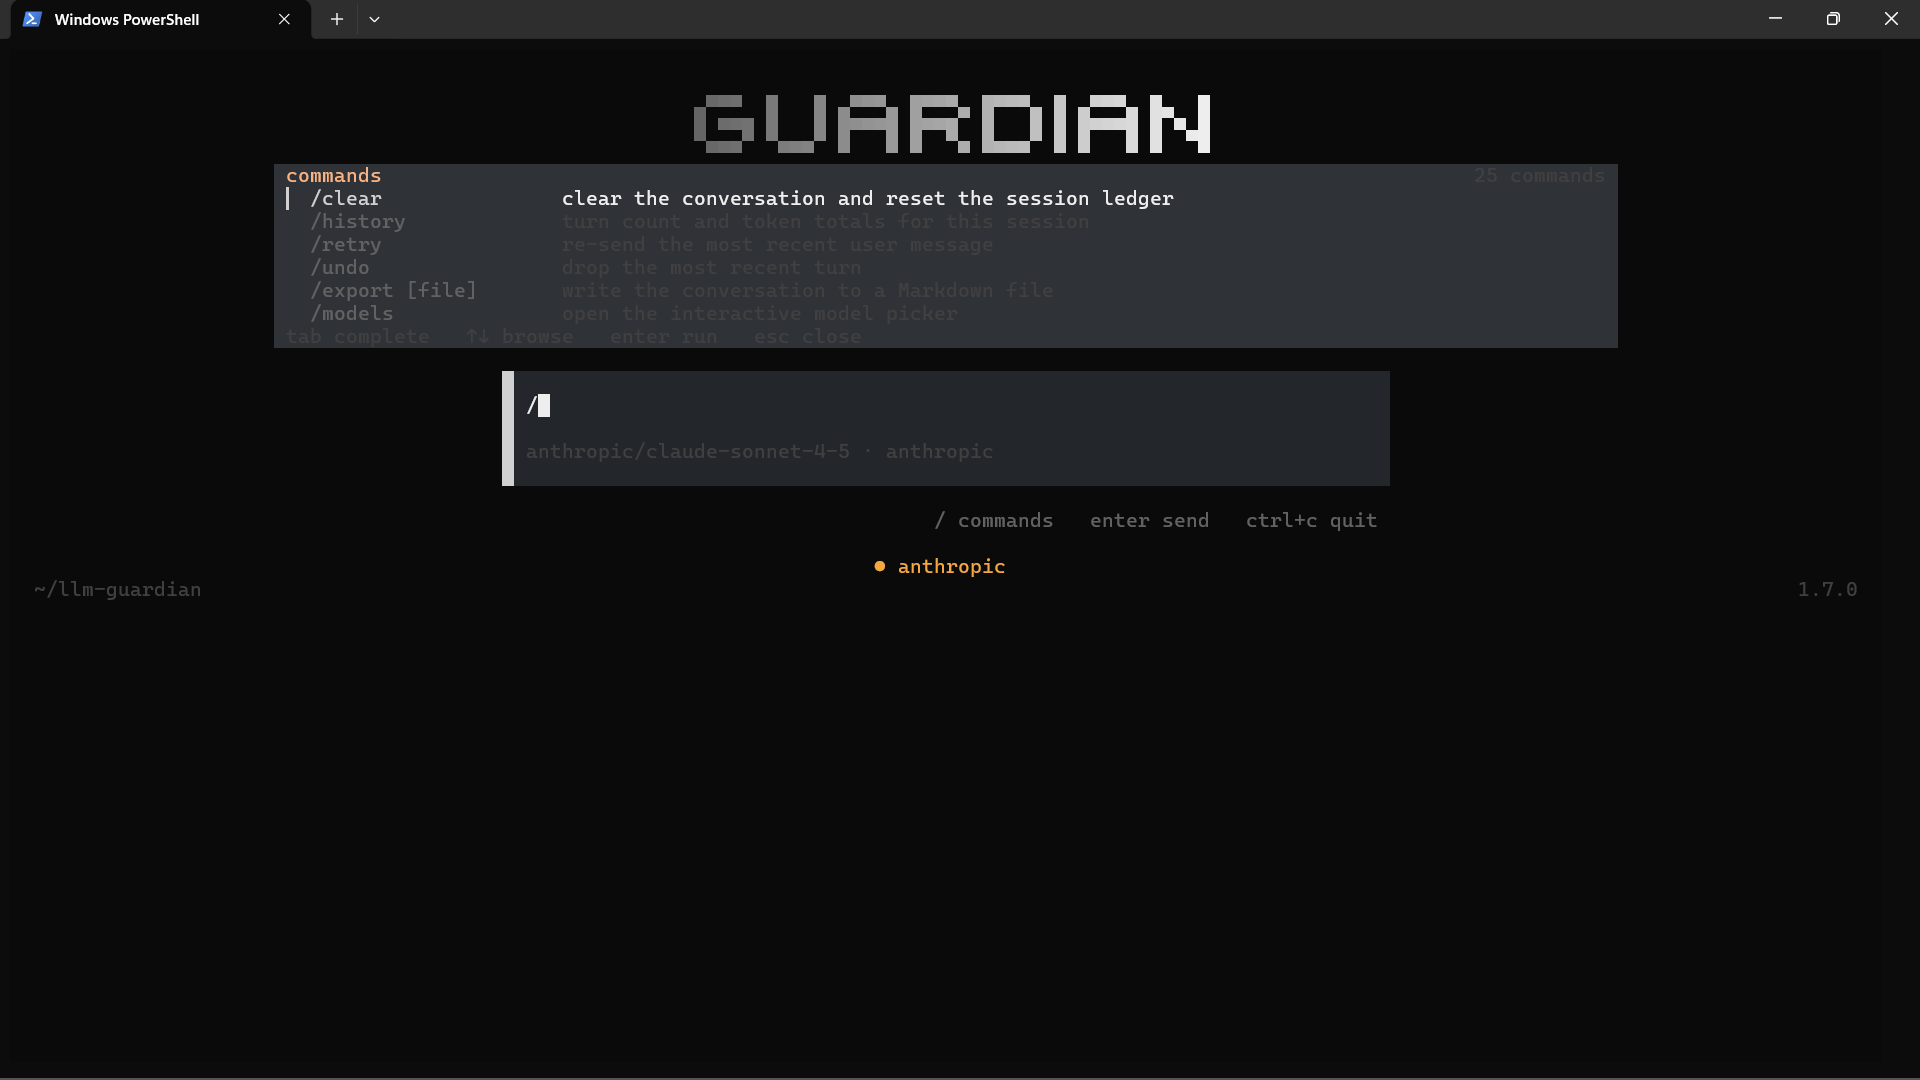
The interactive TUI
Chat with any model through the optimization pipeline, with 25 built-in slash commands — budgets, model routing, transcript export, and more.
Optimization pipeline
01retain pre-filter
02tool gating
03semantic folding
04memory injection
05vcm sharding
06prompt caching
Key features
- Semantic Folding — verbose text to entity-dense headlinese
- VCM Sharding — context skeletons with high-relevance shards
- Retain Pre-Filter — drops low-signal turns before folding
- Tool Gating — trims tool schemas to what the query needs
- Prompt Caching — stable prefixes + cache_control breakpoints
- MemOS memory injection — token-budgeted context packs
- Privacy Shield — PII redaction + injection blocking
- Budget enforcement — per-request, daily, and monthly limits
compression
The full pipeline on a typical agent conversation — raw prompt versus what actually reaches the provider.
raw prompt12,408 tok
guardian-compressed2,767 tok